An independent standard for what agents can actually operate.
Every software category is being re-judged on a question its vendors were never built to answer: can an autonomous agent use this without a human babysitting it? AgentQuadrant exists to answer that question in public, one category at a time, and to be wrong in public when we get it wrong.
The buying criteria changed. The reviews did not.
Software review sites measure how software feels to a person: the interface, the onboarding, the support queue. None of that predicts whether an agent can hold a multi-step workflow together inside the same product. That depends on unglamorous things — whether the API schema is coherent, whether a failed call explains itself well enough for a model to recover, how much of the data model is reachable without a human in the loop, and whether machine identities can be granted narrow permissions and revoked.
Those properties decide whether an agent deployment reaches production or quietly stalls, and almost nobody publishes them. So teams buy on brand, wire up an agent, and discover the gaps in month three. We would rather they discover them here, before the contract.
AgentQuadrant rates tools on that basis, names what is missing, and dates every judgement so it can be checked. The ratings are editorial and they are opinionated. They are also falsifiable: the criteria come first, the verdict second.
Three things, all of them checkable.
Quadrants
Category-by-category ratings that place tools on two axes of agent-readiness. 83 tools rated so far, each against published criteria.
See the quadrants →The extensions directory
MCP servers, plugins, Custom GPTs, Skills and agent frameworks, tiered by how far we have verified them and dated with a last-checked stamp.
Browse the directory →Editorials and guides
Practitioner writing on what actually breaks when agents drive real software: buying criteria, migration paths, and the gaps vendors do not advertise.
Read the writing →The people who have already run agents in production.
A rating is only as good as the judgement behind it. The AI Council is a small group of founders, engineers and operators who have shipped agents into real companies, and who put their names to how this site evaluates. Members set and challenge the criteria, review quadrants before publication, and write for the site under their own byline. Founding seats are being filled now.
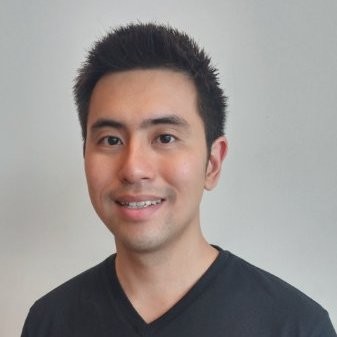
Jiquan Ngiam
Co-founder & CEO, MintMCP
Previously Google and Coursera. Works on agent identity and permissions in the enterprise.
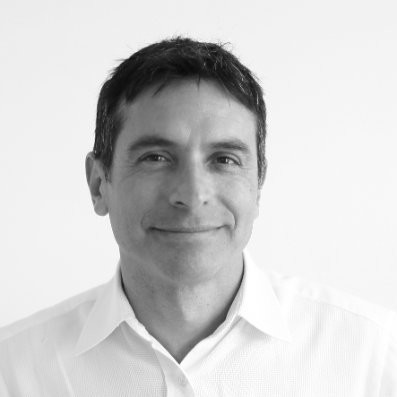
Phillip Bensaid
Co-founder, MintMCP
Previously Disney+ and Amazon. Designs the interfaces teams use to supervise fleets of agents.
Seats open
We are seating founding members who have deployed agents at scale and will argue with a rating in public.
Apply for a seat →Set the criteria
Members define what agent-readiness means in their category and stress-test the axes before a quadrant is drawn.
Review before publication
Draft quadrants go to the council for challenge. Disagreements that survive the evidence get published alongside the rating.
Write under their own name
Editorials carry the member's byline, not a house voice, so readers can weigh who is making the argument.
The obvious objection, answered in writing.
The people who know a category best usually sell into it. Pretending otherwise would be dishonest, so the conflict is managed out in the open instead. These five rules govern the site, and breaking one is grounds for losing a seat.
- A seat never buys a rating.
- Council membership carries no influence over tiers, placement or scores. Members are rated by the same criteria as every other tool, and a member can rate badly.
- Members do not grade their own category.
- Where a member company competes in a quadrant, it has no say in that quadrant: not the axes, not the criteria, not the placements.
- We disclose the overlap.
- Many of the companies worth rating are companies worth having in the room. Where a rated tool belongs to a council member, the entry says so.
- The criteria are public before the verdict.
- Every quadrant publishes the axes and the tests behind it, so a placement can be argued with on the evidence rather than taken on trust.
- Nothing publishes itself.
- Entries come from official registries, public repositories and licensed datasets, then pass editorial review. Vendors cannot write their own listing.
The full tier definitions, data sources and re-verification schedule are on the methodology page. Found a rating we got wrong? Tell us and bring the evidence.
Running agents in production?
Nominate a tool, challenge a placement, or put yourself forward for a founding council seat.